3. Cohorts and manifests#
Most analyses use more than one dataset. A cohort is the client's object for a set of datasets: you build it from
a query, a list of uids or a collection, inspect it from the catalog alone, join its tables into one AnnData,
and freeze it into a manifest that you can load again later and check against the catalog.
The catalog changes between releases. Datasets get new versions, some are withdrawn, and new ones arrive. A script that names data loosely, for example with the newest catalog and a search, can return other data a week later. The sections below show how to make a selection that comes back the same.
You will learn how to:
build a cohort from uids, study ids, a collection or a query, and combine cohorts
summarise a cohort and check which columns are filled
join the tables of several datasets into one
AnnData, with matching gene ids and spatial coordinatesfreeze a cohort, write the manifest, rebuild the cohort from it and verify it
tell a uid, a stem and a
canonical_keyapart, and see what changes between releasesdownload the stores with a manifest that records the catalog version
The downloads below add up to about 30 MB.
import json
import tempfile
import urllib.request
import warnings
from pathlib import Path

import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import scanpy as sc
import spatialdata_plot  # noqa: F401  (adds the .pl accessor to SpatialData)

import sddb
from sddb import CatalogChangedError, CatalogUnavailableError, CohortManifest, Manifest, SpatialDataCohort

cat = sddb.Catalog(version="2026-10-28")
work = Path(tempfile.mkdtemp())  # the files this tutorial writes go here
Build a cohort#
There are four ways to build a cohort, and all of them return a SpatialDataCohort:
cat.query(...)andcat.search(...)filter the catalog (1. Find and filter datasets).cat.cohort(uids=[...])takes the datasets you name, for example from a supplementary table or an earlier analysis.cat.cohort(study_ids=[...])takes every dataset of the studies you name.cat.collection(slug)takes the members of a collection, a grouping that the website shows as a page. The slug is the last part of the page URL.
A collection is a good start when a study deposited several samples together. The collection below is a GEO series of four mouse Visium sections:
series = cat.collection("geo-gse160137")
series.to_df()[["uid", "study_id", "tissue", "n_obs", "size_bytes", "license"]]
| uid | study_id | tissue | n_obs | size_bytes | license | |
|---|---|---|---|---|---|---|
| 0 | EMS0unVubRENrRu80000 | geo:GSM4861204 | trunk | 192 | 4030097 | ncbi-geo-policy |
| 1 | lyqwdGBZ3d0OlAIv0000 | geo:GSM4861203 | trunk | 222 | 4352091 | ncbi-geo-policy |
| 2 | h1okQyQN4GJd0I1l0000 | geo:GSM4861205 | trunk | 178 | 3571112 | ncbi-geo-policy |
| 3 | x38XfjX03r2BgcCf0000 | geo:GSM4861202 | trunk | 198 | 5107000 | ncbi-geo-policy |
cohort() checks every id before it builds anything, so a typo raises a KeyError that names the id, and you
find out before a download starts:
try:
    cat.cohort(uids=["x38XfjX03r2BgcCf0000", "x38XfjX03r2BgcCf0009"])
except KeyError as err:
    print(err)
"unknown uid(s) not in catalog: ['x38XfjX03r2BgcCf0009']"
Cohorts combine like sets. | is the union and - the difference, both by uid. filter(column=value) keeps
the rows with that value, and where(mask) keeps the rows where a boolean mask over members is true.
human_lung = cat.query(organism="human", tissue="lung", technology="Visium")
mouse_lung = cat.query(organism="mouse", tissue="lung", technology="Visium")
lung = human_lung | mouse_lung
print(len(human_lung), "+", len(mouse_lung), "->", len(lung))
print(len(lung.filter(tier="silver")), "silver;", len(lung.where(lung.members["n_obs"] > 3_000)), "with more than 3000 spots")
152 + 89 -> 241
133 silver; 115 with more than 3000 spots
Inspect a cohort#
The methods below read only the catalog rows, so they run in well under a second and download nothing.
lung.summary()
{'n_objects': 241,
 'n_studies': 239,
 'n_without_study_id': 0,
 'technologies': ['Visium']}
lung.groupby("disease").head(6)
| disease | n | |
|---|---|---|
| 0 | normal | 72 |
| 1 | lung adenocarcinoma | 31 |
| 2 | unknown | 19 |
| 3 | obsolete idiopathic pulmonary fibrosis | 19 |
| 4 | lung cancer | 18 |
| 5 | pulmonary fibrosis | 15 |
summary() counts studies by distinct study_id. For GEO data the study_id is the sample accession, so the
four sections of the series above count as four studies even though they come from one experiment:
series.summary()
{'n_objects': 4,
 'n_studies': 4,
 'n_without_study_id': 0,
 'technologies': ['Visium']}
Keep the sample-level study ids in mind when you group datasets by study, for example to keep the samples of one experiment out of both
your training and your test data. The collections and doi columns group samples by series and by publication,
and split(by=...) accepts a function that returns such a key. The
training cohort use case shows a split by GEO series.
coverage() counts, for each column, how many members have a value. Look at it before you filter or group on a
column, because missing values never match a filter.
coverage = lung.coverage().set_index("field")
coverage.loc[["tissue", "disease", "doi", "publication_year", "condition", "mpp", "n_transcripts"]]
| present | unknown | |
|---|---|---|
| field | ||
| tissue | 241 | 0 |
| disease | 241 | 0 |
| doi | 103 | 138 |
| publication_year | 103 | 138 |
| condition | 143 | 98 |
| mpp | 240 | 1 |
| n_transcripts | 0 | 241 |
One AnnData from many tables#
to_anndata() reads only the table of each member, not its images or shapes, and joins the tables into one
AnnData with an outer join on the genes. obs["uid"] and obs["study_id"] record which dataset each row came
from. table= picks the table by name, and the default is each member's default_table.
adata = series.to_anndata()
adata
AnnData object with n_obs × n_vars = 790 × 53574
    obs: 'in_tissue', 'array_row', 'array_col', 'spot_id', 'region', 'uid', 'study_id'
    obsm: 'spatial'
    layers: 'csc_counts'
adata.obs["uid"].value_counts()
uid
lyqwdGBZ3d0OlAIv0000    222
x38XfjX03r2BgcCf0000    198
EMS0unVubRENrRu80000    192
h1okQyQN4GJd0I1l0000    178
Name: count, dtype: int64
Gene ids: gene_key=#
Sources name genes differently. 10x data and most GEO uploads use gene symbols as var_names, and HEST uses
Ensembl ids. Two such tables share no column names, so an outer join puts the same gene in two columns. The next
cohort pairs a GEO Visium section of a human pancreas (symbols) with a HEST Visium section of human skin (Ensembl
ids):
mixed = cat.cohort(uids=["qEP9pd4LlyKeufe20000", "USx288NLowiqKbV30000"])
mixed.to_df()[["uid", "source", "tissue", "n_obs", "n_features"]]
| uid | source | tissue | n_obs | n_features | |
|---|---|---|---|---|---|
| 0 | USx288NLowiqKbV30000 | hest | skin of body | 691 | 19850 |
| 1 | qEP9pd4LlyKeufe20000 | geo | pancreas | 1142 | 17943 |
with warnings.catch_warnings(record=True) as caught:
    warnings.simplefilter("always")
    as_stored = mixed.to_anndata()
print(as_stored.shape)
for warning in caught:
    if "share" in str(warning.message):
        print(warning.message)
(1833, 37793)
members share 0 genes, 0% of the smallest member's 17943; pass gene_key='ensembl' or 'symbol' to align gene ids across sources
The two tables have 17943 and 19850 genes, and the joined table has 37793 columns, their sum. The client warns
when the members share fewer than half the genes of the smallest one. gene_key="ensembl" renames every member's
genes to Ensembl ids before the join, using the column that holds them (var["gene_ids"] in the GEO table).
gene_key="symbol" does the same with symbols.
aligned = mixed.to_anndata(gene_key="ensembl")
print(aligned.shape)
aligned.var[["original_var_name"]].head(3)
(1833, 20035)
UserWarning: Variable names are not unique. To make them unique, call `.var_names_make_unique`.
UserWarning: gene_key='ensembl': dropped 0 features without an Ensembl id and 2 duplicates across 1 members
| original_var_name | |
|---|---|
| ENSG00000000003 | ENSG00000000003 |
| ENSG00000000005 | ENSG00000000005 |
| ENSG00000000419 | ENSG00000000419 |
Now the two tables share their genes. Features without an Ensembl id are dropped, and a gene id that appears twice
in one table keeps its first column. The HEST table has two such repeats, and the warning reports them. The old
name stays in var["original_var_name"].
Spatial coordinates: spatial=#
Most tables store the position of each observation in obsm["spatial"]. Some do not. The Allen Institute
MERSCOPE tables, for example, keep the cell positions only in the shapes element that the table annotates. The
default spatial="auto" keeps a stored obsm["spatial"] when it is complete, and otherwise uses the centres of
the annotated shapes. spatial="obsm" keeps only what the table stores.
The next cohort is two MERSCOPE sections of human basal ganglia from the Allen Institute. Each table also contains 15
blank control probes whose gene name is missing. A missing name cannot be joined on, so to_anndata drops those
features and says so in a warning.
merscope = cat.cohort(uids=["rdngUwLr6XlVEmpD0000", "q2KtN8CbBD73UNei0000"])
for mode in ["obsm", "auto"]:
    with warnings.catch_warnings(record=True) as caught:
        warnings.simplefilter("always")
        joined = merscope.to_anndata(spatial=mode)
    print(*{str(w.message) for w in caught if "var_name" in str(w.message)}, sep="\n")
    xy = joined.obsm.get("spatial")
    missing = joined.n_obs if xy is None else int(np.isnan(np.asarray(xy, dtype=float)).any(axis=1).sum())
    print(f"spatial={mode!r}: {missing} of {joined.n_obs} cells without coordinates")
dropped 30 features with a missing or empty var_name in members ['q2KtN8CbBD73UNei0000', 'rdngUwLr6XlVEmpD0000']; pass gene_key='ensembl' or 'symbol' to merge them instead
spatial='obsm': 35830 of 35830 cells without coordinates
dropped 30 features with a missing or empty var_name in members ['q2KtN8CbBD73UNei0000', 'rdngUwLr6XlVEmpD0000']; pass gene_key='ensembl' or 'symbol' to merge them instead
spatial='auto': 0 of 35830 cells without coordinates
fig, axes = plt.subplots(1, 2, figsize=(11, 4.5))
for ax, ds in zip(axes, merscope, strict=True):
    member = ds.to_sdata()
    table = member.tables[ds.default_table]
    sc.pp.calculate_qc_metrics(table, percent_top=None, inplace=True)  # adds obs["log1p_total_counts"]
    (
        member
        .pl.render_shapes("cell_circles", color="log1p_total_counts", table_name=ds.default_table)
        .pl.show(
            ax=ax,
            frameon=False,
            title=f"{ds.uid}, {table.n_obs} cells",
            colorbar_params={"label": "log(1 + counts per cell)"},
        )
    )
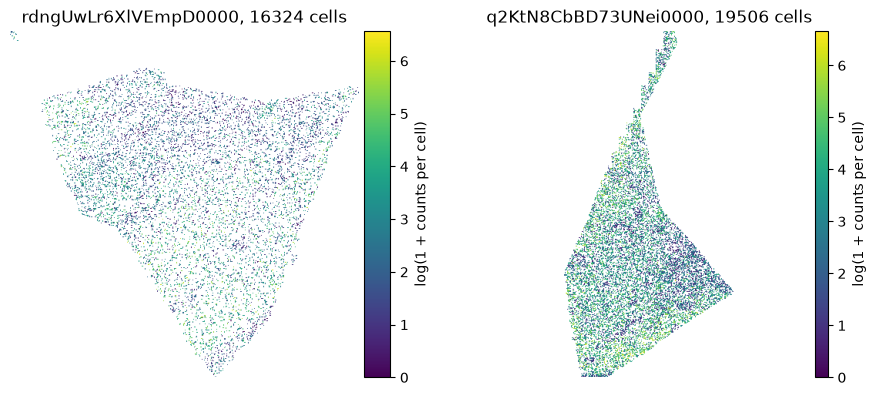
With spatial="obsm" none of the MERSCOPE cells has a position. With the default every cell gets the centre of
its cell circle. The figure draws those cell circles from the two stores with spatialdata-plot, coloured by the
total counts per cell that sc.pp.calculate_qc_metrics adds to each table. A member that has neither a complete obsm["spatial"]
nor annotated shapes keeps missing coordinates, and one warning names it.
Freeze a cohort#
freeze() pins a cohort to its exact members and returns a CohortManifest. The manifest records the full uid
of every member, the filter that built the cohort, the catalog it came from with the sha256 of the catalog file,
and a hash over the filter and the uids. Freezing reads nothing from the network.
manifest = series.freeze()
print(manifest.hash)
print(manifest.filter)
print(manifest.source.url)
print(manifest.source.sha256)
sha256:bbf0062c54f9cfeb30a101d9d5b6088c1e0d7e34768bcec153b5346c1e3df67a
{'collection': 'geo-gse160137'}
https://github.com/theislab/spatialdata-db-client/releases/download/catalog-2026-10-28/catalog.parquet
sha256:8336a505c8a8384a3696eec573692ec1877c582533c13e9600dfde4c461dc3ff
write() saves the manifest as JSON. The members are stored with all their catalog columns, and a cohort of more
than 200 members writes them to a parquet file next to the JSON. Keep the manifest with your results.
path = manifest.write(work / "cohort.json")
saved = json.loads(path.read_text())
{key: saved[key] for key in ["schema_version", "source", "filter", "hash", "n_members"]}
{'schema_version': '2',
 'source': {'url': 'https://github.com/theislab/spatialdata-db-client/releases/download/catalog-2026-10-28/catalog.parquet',
  'version': '2026-10-28',
  'sha256': 'sha256:8336a505c8a8384a3696eec573692ec1877c582533c13e9600dfde4c461dc3ff'},
 'filter': {'collection': 'geo-gse160137'},
 'hash': 'sha256:bbf0062c54f9cfeb30a101d9d5b6088c1e0d7e34768bcec153b5346c1e3df67a',
 'n_members': 4}
SpatialDataCohort.from_manifest() rebuilds the cohort from the file without a catalog query, so it gives the
same members even after the catalog has changed:
restored = SpatialDataCohort.from_manifest(CohortManifest.load(path))
print(restored)
print("same members:", list(restored.members["uid"]) == list(series.members["uid"]))
print("same hash:", restored.freeze().hash == manifest.hash)
<SpatialDataCohort: 4 datasets>
same members: True
same hash: True
Verify a cohort#
A frozen cohort can still go stale in two ways: the catalog file it came from can change, and a store can stop
resolving when a dataset is republished. verify() checks both. First it downloads the catalog again from the
recorded URL and compares its sha256 with the recorded one. Then it checks that every member's store exists.
restored.verify()  # returns None when the catalog is unchanged and every store resolves
print("verified")
verified
Each failure raises its own error:
CatalogChangedErrorwhen a dated release no longer has the recorded sha256. For the rollingcatalog-latesta change is expected, soverify()only warns.CatalogUnavailableErrorwhen the catalog URL cannot be fetched.verify()never falls back to a cached copy, because a cached copy cannot show that the published file changed.CohortDriftErrorwhen a member's store no longer resolves. Itsdriftedattribute maps each uid to the reason.
To see the first two, we copy the catalog file to a local folder, open it with Catalog.from_file and freeze the
same cohort from it. Then we change the file and verify, and finally delete the file and verify again.
local_file = work / "catalog-2026-10-28.parquet"
urllib.request.urlretrieve(cat.url, local_file)
local = sddb.Catalog.from_file(local_file)
frozen = local.collection("geo-gse160137")

# Change the file: drop one row that is not in the cohort.
rows = pd.read_parquet(local_file)
rows[rows["uid"] != rows["uid"].iloc[-1]].to_parquet(local_file)
try:
    frozen.verify()
except CatalogChangedError as err:
    print("CatalogChangedError:", str(err)[:110], "...")

local_file.unlink()
try:
    frozen.verify()
except CatalogUnavailableError as err:
    print("CatalogUnavailableError:", err.reason[:80])
CatalogChangedError: catalog at /tmp/sddb-docs-tmp/tmpl_vucjtw/catalog-2026-10-28.parquet was modified after the cohort was frozen: ...
CatalogUnavailableError: FileNotFoundError: catalog not found: /tmp/sddb-docs-tmp/tmpl_vucjtw/catalog-202
from_manifest(m, catalog=cat) runs the same sha256 check against a catalog you already opened, so you can check
a manifest without a second download.
Releases, uids, stems and canonical keys#
Catalog() without version reads catalog-latest, which changes with every release.
Catalog(version="2026-10-28") reads the dated release, which does not change. A dataset can be named in three
ways:
The uid, such as
qEP9pd4LlyKeufe20000, has 20 characters and names one version of one dataset. The last four characters count the versions.The stem is the first 16 characters of the uid.
Catalog.datasetresolves a stem to whichever version the catalog you opened has, so the same stem can give different data in a later release.The
canonical_key, such asgeo:GSM8915497, names the source record. It usually survives a new version of the dataset, but not every dataset has one.
To see how much changes between releases, compare the 2026-10-28 release with the one from 16 October 2026:
old = sddb.Catalog(version="2026-10-16").to_df()
new = cat.to_df()
old_stem, new_stem = old["uid"].str[:16], new["uid"].str[:16]

same_stem = old.assign(stem=old_stem).merge(new.assign(stem=new_stem), on="stem", suffixes=("_old", "_new"))
reversioned = same_stem[same_stem["uid_old"] != same_stem["uid_new"]]
withdrawn = old[~old_stem.isin(set(new_stem))]
print(len(old), "datasets on 2026-10-16,", len(new), "on 2026-10-28")
print(len(reversioned), "datasets have a new version (new uid, same stem)")
print(len(withdrawn), "stems from 2026-10-16 are not in 2026-10-28")
print(int(withdrawn["canonical_key"].isin(set(new["canonical_key"].dropna())).sum()), "of those have a canonical_key that is still in the catalog")
1774 datasets on 2026-10-16, 6087 on 2026-10-28
84 datasets have a new version (new uid, same stem)
138 stems from 2026-10-16 are not in 2026-10-28
39 of those have a canonical_key that is still in the catalog
A uid from the older release is not in the newer one when the dataset got a new version. Its stem resolves to the new version:
old_uid, new_uid = reversioned.iloc[0][["uid_old", "uid_new"]]
try:
    cat.dataset(old_uid)
except KeyError as err:
    print("KeyError:", err)
print(old_uid[:16], "->", cat.dataset(old_uid[:16]).uid)
KeyError: "uid not in catalog: 'IlEA4ms6c9S1OvBg0004'"
IlEA4ms6c9S1OvBg -> IlEA4ms6c9S1OvBg0005
The canonical_key helps when a dataset was uploaded again under a new stem, but it is no guarantee. Of the 138
stems that are gone, only 39 have a canonical_key that the newer release still has, and some datasets have no
key at all.
check_updates(catalog) lists the members of a cohort that a catalog has replaced with a newer version, as
{old uid: new uid}. Run it with the newest catalog to see whether a frozen cohort is out of date:
old_cohort = sddb.Catalog(version="2026-10-16").cohort(uids=list(reversioned["uid_old"].iloc[:3]))
old_cohort.check_updates(cat, warn=False)
{'IlEA4ms6c9S1OvBg0004': 'IlEA4ms6c9S1OvBg0005',
 'iHSXYBFbeAMN3zxa0000': 'iHSXYBFbeAMN3zxa0001',
 'xTLyS1AdjfKzI25v0000': 'xTLyS1AdjfKzI25v0001'}
For a result you want to reproduce, record the release date and the full uids, or keep the manifest from
freeze(). Use a stem or a canonical_key only to look up the current version of a dataset, and record the uid
that comes back.
Download with a manifest#
download(dest) copies every member's store to dest/<uid>.zarr and writes dest/manifest.json. It runs in
parallel and can be resumed: a second call skips the stores that are complete. pin_versions=True records the
catalog release in the manifest, and a later download into the same folder from another release raises
ManifestVersionMismatch unless you pass allow_version_change=True.
data = work / "gse160137"
downloaded = series.download(data, pin_versions=True)
print("catalog_version:", downloaded.catalog_version)
for entry in downloaded.entries:
    print(entry.uid, entry.status, f"{entry.size_bytes / 1e6:.1f} MB")
catalog_version: 2026-10-28
EMS0unVubRENrRu80000 complete 4.0 MB
lyqwdGBZ3d0OlAIv0000 complete 4.4 MB
h1okQyQN4GJd0I1l0000 complete 3.6 MB
x38XfjX03r2BgcCf0000 complete 5.1 MB
again = series.download(data, pin_versions=True)  # nothing to fetch, every store is complete
sorted(p.name for p in data.iterdir())
['EMS0unVubRENrRu80000.zarr',
 'h1okQyQN4GJd0I1l0000.zarr',
 'lyqwdGBZ3d0OlAIv0000.zarr',
 'manifest.json',
 'x38XfjX03r2BgcCf0000.zarr']
Manifest.read() loads the file, and refetch(dest) copies the recorded stores again from the recorded URLs, for
example on another machine. The sha256 in each entry covers the file names and sizes of the store, not the file
contents.
recorded = Manifest.read(data / "manifest.json")
[(entry.uid, entry.status, entry.sha256[:12]) for entry in recorded.entries]
[('EMS0unVubRENrRu80000', 'complete', '186ae4615290'),
 ('lyqwdGBZ3d0OlAIv0000', 'complete', '6747d2170781'),
 ('h1okQyQN4GJd0I1l0000', 'complete', '2eb809f75d0c'),
 ('x38XfjX03r2BgcCf0000', 'complete', 'e8504e7e19af')]
to_list() and to_dict() open the members as SpatialData objects, from the cache or, with dest=, from a
folder laid out like download(). They accept elements= like Dataset.to_sdata.
by_uid = series.to_dict(dest=data)
{uid: list(sdata.tables) for uid, sdata in by_uid.items()}
{'EMS0unVubRENrRu80000': ['table'],
 'lyqwdGBZ3d0OlAIv0000': ['table'],
 'h1okQyQN4GJd0I1l0000': ['table'],
 'x38XfjX03r2BgcCf0000': ['table']}
Summary#
Build cohorts with
query,cohort(uids=...),cohort(study_ids=...)orcollection(slug), and inspect them withsummary,groupbyandcoveragebefore you download.For GEO data a
study_idis one sample, so group bycollectionsordoito keep an experiment together.to_anndata(gene_key=...)puts genes from different sources under one id type, andspatial="auto"fills coordinates from the shapes when a table stores none.Pin
Catalog(version=...),freeze()the cohort, keep the manifest andverify()it. A uid names one version, a stem and acanonical_keyname the latest one.download(dest, pin_versions=True)writes the stores with a manifest that records the release.
Next: 4. Citations and licenses, on what you must cite and what the licenses of your cohort allow.